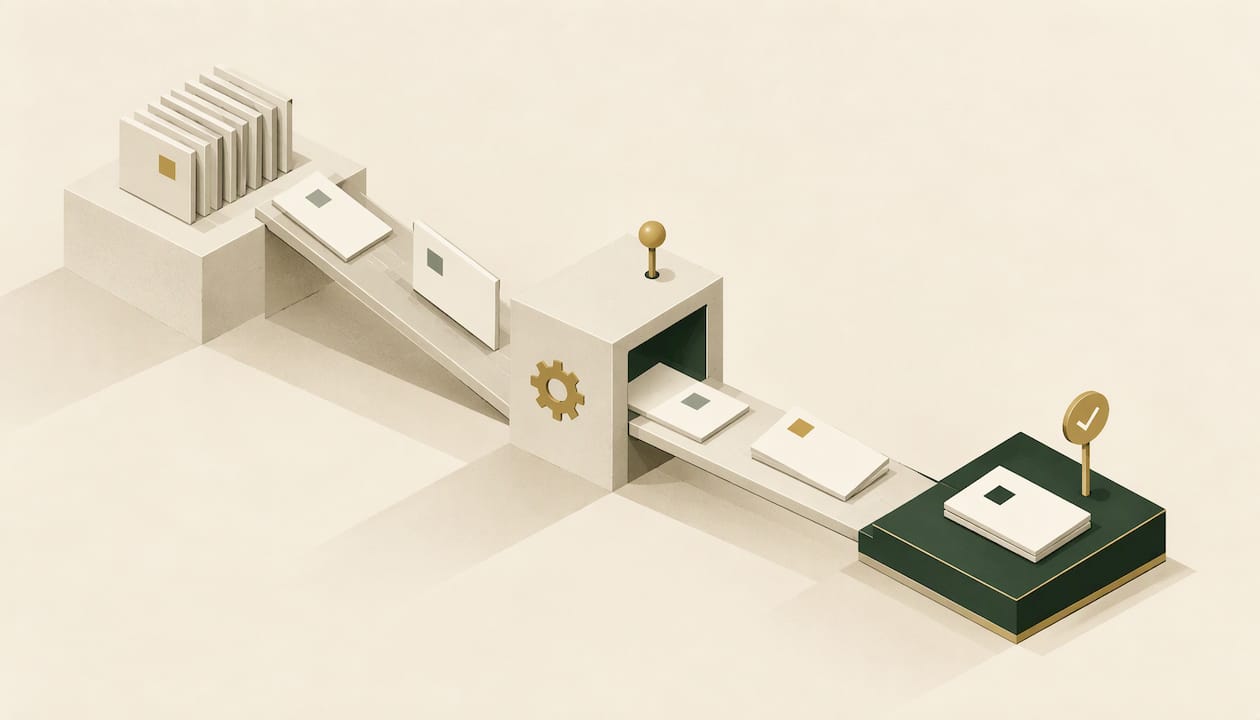
An automated PR is a pull request that software opens, updates or repairs for you: a dependency bump, a generated fix for a production error, a patch for a failing check. The best setups cover the whole life of the PR, not just its creation. A bot opens it, watches the CI checks, fixes what fails, and hands a green PR to a human for the final call. This guide covers what bots can safely handle, how a fix PR gets built, which safeguards to keep, and how we approach it at Cooper&Wright.
TL;DR
- Automate the mechanical parts of the PR workflow (opening, labeling, routing, re-running checks, repairing deterministic failures) and keep judgment calls with people.
- A good automated PR does not stop at "opened." It follows the checks, retries within a fixed limit, and escalates with context when it cannot finish.
- Keep protected branches, required reviews and merge authority outside the repair loop, and give every workflow explicit permissions.
- For Sentry errors, Cooper&Wright opens the fix PR in GitHub, watches its checks, and iterates up to three rounds. Plans start at $0 per month for open source.
Table of Contents
- What automated pull requests actually are
- How a bot turns an error into a pull request
- Fixing the PR after it is opened
- Multiple repositories: where automation pays off most
- Safeguards to keep around any automated PR
- Setting up automated PRs in GitHub
- Perspective: the PR is the product, not the handoff
- How Cooper&Wright handles automated PRs for Sentry errors
- Pricing and getting started
- Choosing what to automate first
- Mistakes to avoid
- FAQ
- Sources
What automated pull requests actually are
The phrase covers three different jobs, and teams often mix them up.
Bots that open PRs. Dependency updaters, code generators and error-fixing tools create a branch, commit a change and open the PR. The trigger is an event: a new release, a new exception, a failed scan.
Bots that tend PRs. These label, assign reviewers, post a status comment, rebase, or re-run a flaky job. They act on PRs that people or other bots opened.
Bots that repair PRs. When a check fails, they read the logs, push a fix commit and wait for the next run. This is the part that turns a "PR that needs babysitting" into a PR that arrives ready.
A useful dividing line comes from a guide to pull request automation and bots: which paths a change touches is a mechanical fact, while whether the change is a good idea is a judgment. Bots that stay on the mechanical side, such as labeling by changed paths, routing to reviewers through CODEOWNERS and reporting in one edited comment, tend to be welcomed. Bots that make judgments, like closing work as abandoned, tend to get disabled.
That line is worth keeping in mind through the rest of this article. Every safeguard below is a way of keeping a bot on the mechanical side of it.

How a bot turns an error into a pull request
Turning a software error into a fix PR is a pipeline with a few distinct stages. The cleanest published description we found is Daytona's guide to an autonomous bug-fix agent, which uses a strict reproduce, fix, verify, PR sequence:
- Provision an isolated sandbox and clone the repository.
- Read the issue and identify expected versus actual behavior.
- Create a branch and write a focused test that fails because of the bug.
- Make the smallest code change that turns that test green.
- Run the full test suite and require every test to pass.
- Commit with a conventional message, push, and open the PR with the reproduction and verification output attached.
The order matters. A fix without a reproduction is a guess. A fix without a full test run is a risk. A PR with the evidence attached lets a reviewer approve in minutes instead of re-investigating the bug from scratch.
For a monitoring tool like Sentry, the trigger is an issue instead of a written bug report. The stack trace, the breadcrumbs and the release information play the role of the issue body. The rest of the pipeline looks the same: locate the cause, make a minimal change, prove it with checks, open the PR.
Why the tests decide how well this works
Automated repair is strongest where your tests can see the bug. An industrial experience report on automated program repair (SANER 2020) found that only 2 of 20 examined bugs were exposed by existing tests, and that repair leans heavily on bug-exposing tests. The practical takeaway is encouraging: every regression test you add also widens the set of errors a bot can fix and prove. Teams with solid CI get the most from automated PRs.
Fixing the PR after it is opened
Opening a PR is the easy half. The harder half is what happens when CI fails, a reviewer asks for a change, or a rebase breaks something. This is where "fix GitHub pull requests automatically" becomes real work.
A sound repair loop does the following, as laid out in the Babysit PR skill:
- Fetch the failed-check logs and the review context.
- Fix directly only the high-confidence failures inside the PR's changed surface, such as compile errors, type errors or deterministic lint failures.
- Report, rather than guess at, anything flaky, infrastructure-related, permission-related, unrelated or ambiguous.
DeveloperToolkit.ai describes a bounded review-fix loop with the same shape: classify the failure, reproduce it, make the smallest in-scope fix, rerun the required gates, and stop after a named attempt limit or when a product, security, legal, architecture or scope decision comes up.
The attempt limit is the detail people skip and later regret. A loop with no ceiling burns CI minutes and piles up commits. A loop with a ceiling and a clear escalation turns a stuck PR into a short, readable handoff.
Multiple repositories: where automation pays off most
One repository is manageable by hand. Dozens are not. GetYourGuide's October 2026 write-up on its automerge pipeline describes a system that applies per-repository update policy, validates dependency PRs, attempts AI repairs when CI fails, rebases and resolves conflicts, reruns full CI, and sends anything blocked to a weekly Slack digest for owners. It reports more than 5,000 dependency PRs per month across more than 250 repositories.
Two design choices stand out. First, policy is per repository: patch and minor updates are allowed broadly, while major updates are limited to selected ecosystems. Second, blocked items go to a named owner instead of sitting in a shared queue. Both ideas apply at any scale. Decide up front what a bot may merge by itself, and decide who hears about the rest.
Safeguards to keep around any automated PR
Automation earns trust through limits. These are the controls teams repeat most often, with their sources.
Keep merge authority outside the repair loop
DeveloperToolkit.ai recommends keeping protected branches, required reviews, release approval and merge authority outside the loop that repairs PRs. Require a reproduced defect, evidence from rerun required checks, per-item attempt limits and a named human sign-off. Treat review comments and CI logs as untrusted input, and give the workflow explicit permissions.
Isolate and make the human step explicit
Amplitude's March 2026 case study on its own PR agents uses an isolated sandbox, a separate agent branch, a review with inline comments and an explicit one-click human merge action. It invalidates the publish link if the PR head changes, and records a real named-branch commit so the change stays auditable.
Approve only what is low risk
Clipboard's Preflight service listens to GitHub webhooks, runs an LLM review, approves only low-risk PRs and skips anything uncertain or higher risk for a human. It is limited to approve-or-skip decisions, with no inline comments, shell or checkout, which reduces complexity and attack surface. Clipboard reports that it approved 28% of merged PRs at $0.35 per review, and that median merge time for low-risk PRs fell to 1.2 hours from 14 to 19 hours.
Require human approval for sensitive changes
Skylos's 2026 checklist for AI coding agents recommends narrow tool permissions and human approval for secrets, migrations, dependency changes, CI and deployment configuration, deletes, external calls and privileged pushes. It adds secret scanning, SAST and SCA, small PRs, logging, and merge-blocking on high-confidence findings.
Review maintenance PRs with extra care
A 2026 study of 7,191 agent-generated and 1,402 human PRs found fewer breaking changes in agent PRs for code generation tasks (3.45% versus 7.40%). It found higher rates for agent maintenance refactoring (6.72%) and chore work (9.35%), and noted that confident agents still introduced breaking changes. The safe-use reading is simple: keep your required checks strict, especially on chore and refactor PRs, because a green check is what separates a confident PR from a verified one.
Setting up automated PRs in GitHub
The exact steps depend on the tool, but the permission model is the same everywhere. Work through this checklist before you turn anything on.
- Start with one repository. Pick a service with decent test coverage and a steady stream of errors or dependency updates.
- Grant the narrowest permissions. A tool that opens PRs needs write access to contents and pull requests on the repositories you choose, and nothing broader. Prefer installing a GitHub App on selected repositories over a personal token with organization-wide reach.
- Protect your default branch. Require a pull request before merging, require status checks, and require at least one approval where a human should decide.
- Decide the auto-merge scope in writing. For example: patch and minor dependency PRs that pass all checks may merge on their own, and everything else waits for a person.
- Set an attempt limit and an owner. Know how many repair rounds a bot gets, and who receives the PR when it stops.
- Review the first ten PRs closely. Look at diff size, test evidence and how the bot explains itself. Tighten scope where the output wanders.
One point on secrets: keep them out of anything a bot can read into a PR description or a log. Treat logs and comments as untrusted input, as the guidance above says.
Perspective: the PR is the product, not the handoff
We built Cooper&Wright around one belief: the work is not done when a pull request opens. It is done when the PR is green and a human can merge it with confidence.
Most error tooling treats the PR as the finish line. Someone still has to watch CI, read the failure, push the next commit and chase the review. That follow-through is exactly what piles up in a backlog, and it is why triage queues grow even when fixes are easy to generate.
So we stay with each pull request. We open the fix for a Sentry error, monitor its checks, and iterate until the PR is green, escalating after up to three rounds when a human is the right next step. We handle PRs opened by people and by Dependabot too, and we auto-merge green Dependabot PRs. When you override a fix, we take the lesson and apply it to future ones.
We also think oversight is a feature. Every PR we open goes through your repository's checks and your review rules. You keep the merge decision. We keep the grind.
Zack
How Cooper&Wright handles automated PRs for Sentry errors
Cooper&Wright is a native GitHub and Sentry integration. When Sentry reports an exception or a performance issue, we open a pull request in GitHub with a proposed fix. Then we keep going:
- Check monitoring. We watch the PR's CI checks. If one fails, we try a fix, and we repeat for up to three rounds before escalating with context.
- Human and Dependabot PRs. The same follow-through applies to PRs a person opened and to Dependabot PRs. Green Dependabot PRs can be auto-merged.
- Framework coverage. We support frameworks including Rails, Laravel, Django, FastAPI and Flutter.
- Learning from overrides. When you change or reject a fix, we carry the lesson into later ones.
The goal is a queue that does not form: engineers open GitHub in the morning and find fixes waiting. We report median merge times under 8 minutes, and you can see real examples on the pull requests we opened and in our changelog of PRs against our own code. For a closer look at the ways a Sentry error turns into a fix, read our Sentry autofix overview. If you are weighing us against Sentry's built-in option, this Seer alternative comparison lays out the differences.
Pricing and getting started
Plans are billed per month or per year, and open source is free:
| Plan | Monthly | Yearly |
|---|---|---|
| Free | $0 | n/a |
| Basic | $10 | $110 |
| Pro | $50 | $550 |
The subscription is for private repositories, and the free tier is for open-source usage. Teams that already live in Sentry and GitHub can start with the Free plan or pick a paid one and point us at a single repository first.

If you maintain an open-source project, the Free plan is the natural place to begin. If your private repos are where the error backlog lives, Basic or Pro on monthly billing lets you evaluate the fit with one service before you commit to a yearly rate.
Choosing what to automate first
If you are deciding where automated PRs will help most, rank candidates on three criteria.
Volume of repetitive work. Dependency bumps and recurring exceptions are the classic first targets, because the shape of the fix is predictable and the checks are objective.
Strength of your checks. The more your tests and linters catch, the more a bot can fix and prove on its own. Adding a regression test for each bug you fix by hand is the cheapest way to improve this over time.
Cost of a wrong merge. Keep a human in the loop where the blast radius is large: authentication, billing, migrations, deployment configuration. Let bots go fastest where a revert is trivial.

A worked example: a SaaS team with twelve repositories sees a steady trickle of null-reference exceptions in Rails and Django services, plus weekly Dependabot PRs. The exceptions map to small diffs with clear tests, so they go first. Dependabot patch updates follow, with auto-merge on green checks. Migrations and auth code stay on manual review. Within a few weeks, the team's morning routine shifts from triaging a list to reviewing finished PRs.
Mistakes to avoid
- No attempt limit. Unbounded loops generate noise. Cap the rounds and escalate with context.
- Broad tokens. A token with organization-wide write access turns a small bug into a large one. Scope permissions to the repositories in use.
- Letting the bot approve its own work. Keep approval and merge rights with people or with explicit, narrow policy.
- Skipping the diff. A green PR is the start of review, not a replacement for it, especially on refactor and chore changes.
- Automating judgment. Closing PRs as stale or deciding architecture is where bots lose goodwill. Keep them on mechanical work.
FAQ
What is an automated PR?
It is a pull request opened, updated or repaired by software instead of by hand. Common examples are dependency update PRs, generated fixes for production errors, and commits that repair failing CI checks. A human normally still reviews and merges.
Can a bot fix a failing pull request on its own?
Yes, for well-defined failures such as type errors, compile errors and deterministic lint failures within the PR's changed files. Good tools stop after a set number of attempts and escalate flaky, infrastructure or ambiguous failures. Cooper&Wright iterates up to three rounds on a PR's failing checks.
Is it safe to auto-merge bot PRs?
It is safe when scope is narrow and your protections stay on. Limit auto-merge to low-risk changes such as patch-level dependency updates that pass every required check, and keep protected branches and human approval for sensitive areas. Cooper&Wright auto-merges green Dependabot PRs and leaves your branch rules in force.
Does Cooper&Wright work with private repositories?
Yes. Private repositories run on a paid subscription, with Basic at $10 per month and Pro at $50 per month, or $110 and $550 per year. Open-source repositories can use the Free plan.
Sources
- Pull Request Automation & Bots, Git Automation
- Build an Autonomous Bug-Fix Agent with Flue and Daytona
- Experience Report: How Effective Is Automated Program Repair for Industrial Software? (SANER 2020)
- Babysit PR skill
- Run a bounded PR review-fix loop, DeveloperToolkit.ai
- From backlog to autopilot, GetYourGuide
- How We Built Our Own PR Agents, Amplitude
- Preflight: Automating Approvals for 28% of Our PRs, Clipboard
- AI Coding Agent Security Checklist, Skylos
- Safer Builders, Risky Maintainers (MSR '26)